01
The problem
Security classification needs more than a single overall accuracy number. This project separates the question of whether a connection is malicious from the harder task of identifying its attack family, especially when rare classes are underrepresented.
02
How it works
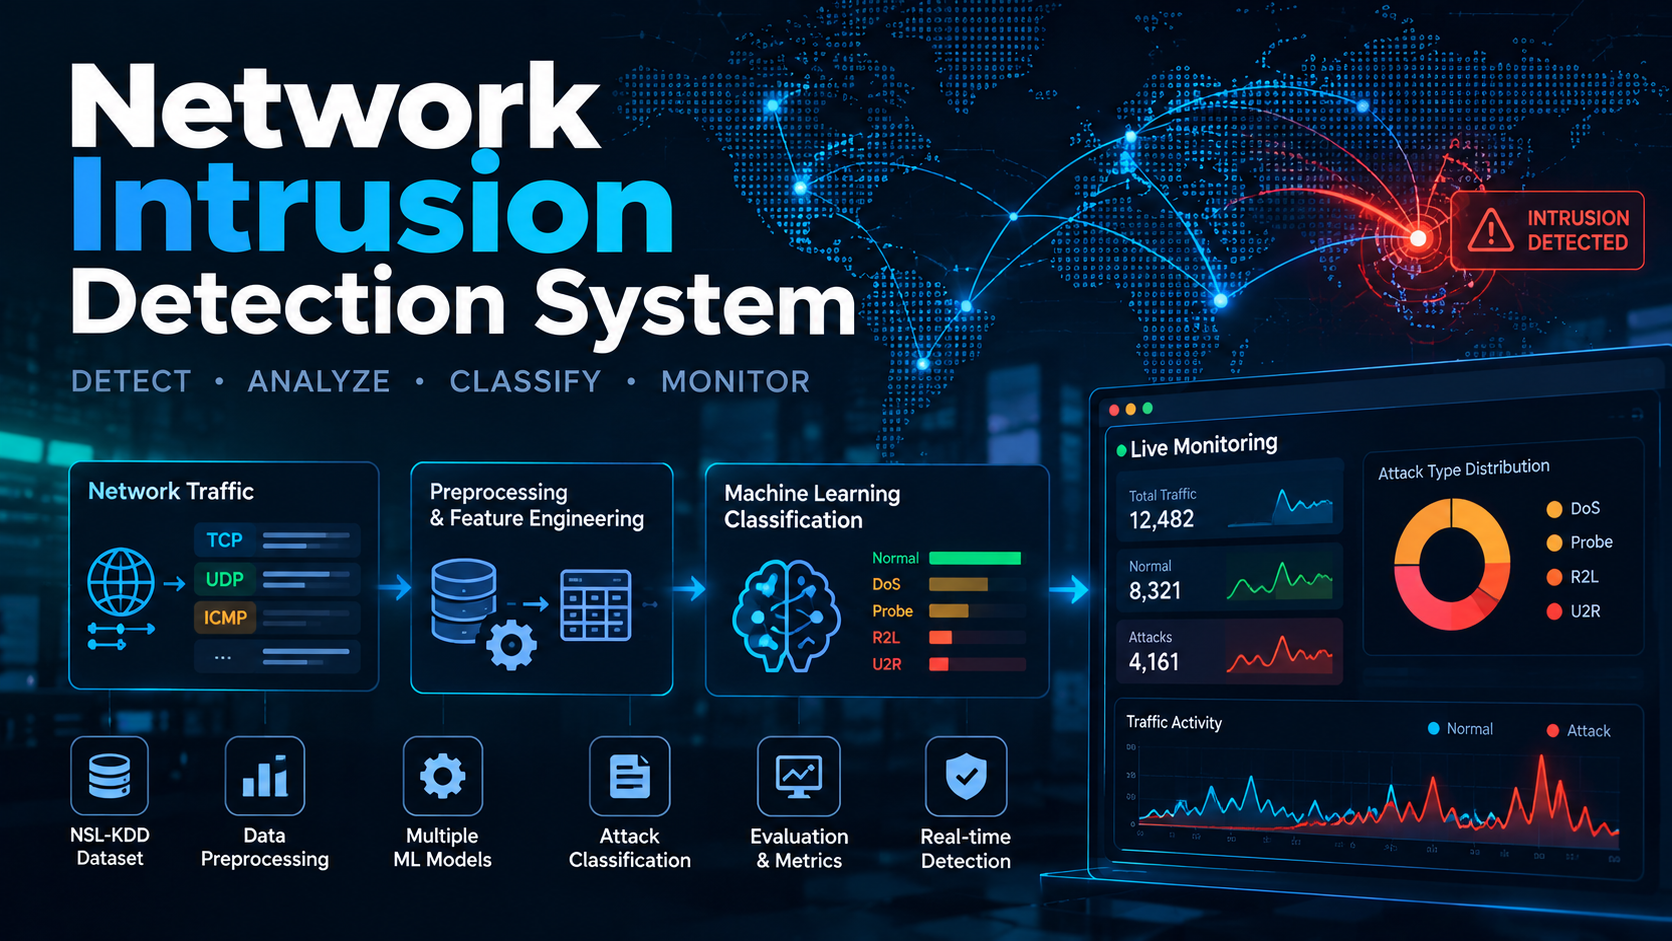
- Inspect the official NSL-KDD train/test split, its 41 connection features, label imbalance, and attack types that appear only in testing.
- Prepare numeric and categorical features, validating missing values and duplicates.
- Compare Logistic Regression, Random Forest, and HistGradientBoosting for binary detection; compare tree-based models for multiclass diagnosis.
- Export models, feature importance, and example connections for a Streamlit demonstration. A separate workflow examines suspicious patterns in web access logs.
03
Reported evaluation
On the repository's documented split, the binary HistGradientBoosting model reports 79.73% accuracy and 78.89% F1. The multiclass model reports 78.14% accuracy but only 55.98% macro F1. That gap makes the rare-class weakness visible rather than hiding it behind aggregate accuracy.
04
Limits
NSL-KDD is a learning benchmark, not a substitute for evaluating modern production traffic. The Streamlit app is a model demonstration, not a production intrusion-prevention system. Benchmark classification and heuristic web-log monitoring are separate capabilities and should not be conflated.
Explore the work
Source code, documentation, and reproducibility notes on GitHub